Now boardingData engineering roles

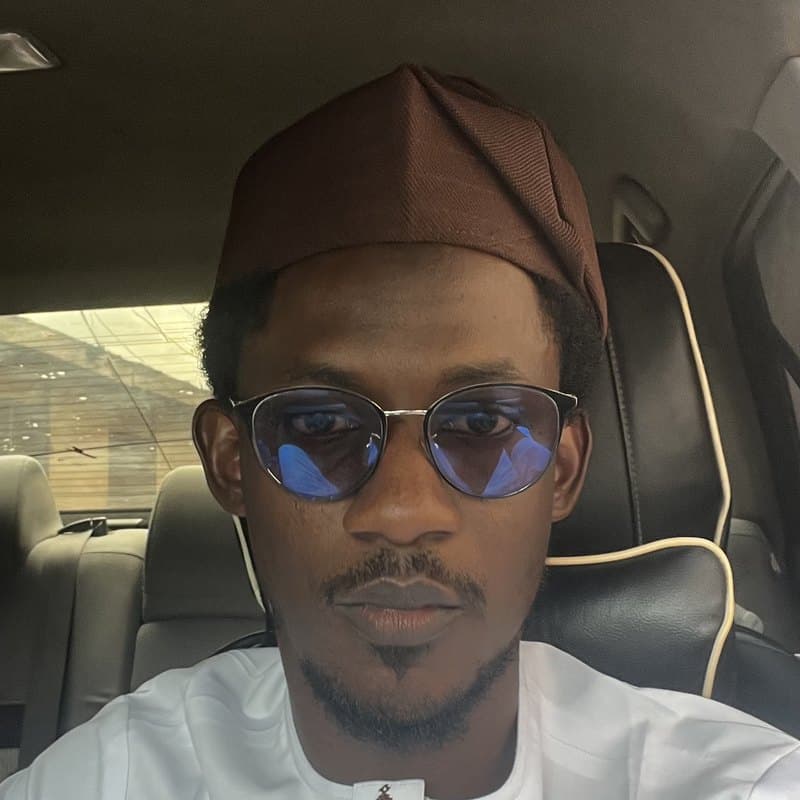
Ahmad Olaitan Alege, Data Engineer

I build the pipelines your data runs on.

4+ years across Microsoft Fabric, Azure, and AWS: ingestion platforms, streaming, dbt models, and financial reconciliation. I've shipped full-stack products too, so I also build the APIs and apps that sit on top of the data.

  • Data line: Data line
  • Cloud line: Cloud line
  • Software line: Software line
next stopyour teamFabricKafkadbtAzureAWSTerraformReactFastAPIOAuth2AHMAD ALEGE
Ahmad Olaitan Alege

Departures · results in production

Data line: Financial reconciliationMTN Fintech>95% auto-matched
Cloud line: Infrastructure costNoji Guardian Protocol$600 → $40 / month
Data line: Airflow ETLZulaiy Technologies500K+ records / day
Software line: Query performanceZulaiy Technologies60% faster

Route history

Four stops, one line of work.

Getting data in reliably, proving it is correct, and building the services around it. Roles that spanned two kinds of work run as parallel lines.

  1. Present

    MTN Fintech

    Data Engineer (Contract)Data line:
    • Engineered automated Microsoft Fabric/ADF pipelines that ingest multi-partner financial statements from SFTP and gateways into Lakehouse Delta tables.
    • Built Python parsing engines for MT940, ISO 20022, CSV, and XLSX with balance validation, file completeness checks, and duplicate transaction detection.
    • Built the core reconciliation engine with automated break analysis, root-cause tagging, and exception categorization, reaching >95% auto-matching on production runs.
  2. Present

    Noji Guardian Protocol

    Cloud & Data EngineerCloud line: Data line:
    • Cut monthly infrastructure cost from over $600 to ~$40 through compute and storage optimization across production and staging.
    • Built cloud-native ingestion and processing pipelines for telemetry and analytics workloads.
    • Automated provisioning and deployments with Terraform, Docker, Kubernetes, and CI/CD, and improved monitoring, logging, and on-call alerting.
  3. Present

    Zulaiy Technologies

    Software and Data EngineerData line: Software line:
    • Designed and operated Airflow and Docker ETL pipelines processing 500K+ records daily across distributed databases.
    • Built backend services and REST APIs in Python and JavaScript secured with OAuth2 and JWT.
    • Reduced query latency by 60% through PostgreSQL and MySQL query and schema optimization, and cut release time by 50% with CI/CD and automated testing.
  4. Space and Form Nigeria Limited

    Data EngineerData line:
    • Designed normalized PostgreSQL and MongoDB schemas alongside dimensional models for reporting.
    • Built Python, dbt, and Airflow transformation pipelines handling 200+ GB of data monthly.
    • Implemented data quality suites with dbt and Great Expectations to protect transactional integrity.

The network

Every system, drawn as the route its data takes.

Streaming ingestion, change data capture, and governed modeling. Each line has a full write-up of the decisions and tradeoffs behind it.

Data line: Software line: Newest line

Pipelight

Interactive Event-Driven Analytics Platform

Storefront events become live business metrics in ~30 seconds, with bad data quarantined, 54 dbt tests per cycle, and failure scenarios you can trigger on demand.

  1. Storefront
  2. FastAPI
  3. Redpanda
  4. Consumer
  5. dbt
  6. Metrics API
  • Delivered a working, observable pipeline from user action to business metric with live freshness and health status.
  • Ran 54 automated dbt tests on every transformation cycle, surfaced in the UI via the Metrics API.
  • Made failure modes demonstrable: bad schemas, duplicates, late data, and spikes can each be triggered and observed end to end.
FastAPIRedpandaPostgreSQLdbtAirflowReactGrafanaDocker
Data line: Cloud line:

Real-Time Crypto Streaming on Azure

Binance trades streamed through Event Hub and Databricks into Bronze, Silver, and Gold Delta tables on a 5-minute cadence.

  1. Binance WS
  2. Event Hub
  3. Databricks
  4. Delta Lake
Case study
Data line:

CDC E-commerce Analytics Pipeline

Row-level PostgreSQL changes captured with Debezium and streamed through Kafka into SCD Type 2 dimensions and fact tables.

  1. PostgreSQL WAL
  2. Debezium
  3. Kafka
  4. SCD2 + facts
Case study
Data line:

dbt E-commerce Analytics Models

Layered staging, intermediate, and mart models with tests and lineage, so reporting uses one definition of orders and revenue.

  1. Raw sources
  2. Staging
  3. Intermediate
  4. Marts
Case study
Browse all projects

Line diagrams

The stack, stop by stop.

Data line

Pipelines & Streaming

Scheduled, testable, restartable ingestion.

  1. Microsoft Fabric
  2. Apache Airflow
  3. Apache Kafka
  4. Kafka Connect
  5. Debezium
  6. PySpark
  7. dbt
  8. Great Expectations

Data line

Storage & Modeling

Models shaped around how data is used.

  1. Delta Lake
  2. PostgreSQL
  3. MySQL
  4. BigQuery
  5. Redshift
  6. MongoDB
  7. ADLS Gen2
  8. Dimensional modeling

Cloud line

Cloud & DevOps

Infrastructure as code, with an eye on cost.

  1. Azure
  2. AWS
  3. Terraform
  4. Docker
  5. Kubernetes
  6. Helm
  7. CI/CD
  8. Grafana

Software line

Software Engineering

Services and frontends, tested like production.

  1. Python
  2. SQL
  3. TypeScript
  4. FastAPI
  5. React / Next.js
  6. REST APIs
  7. OAuth2 / JWT
  8. Pytest

Rules of the line

How I design pipelines that survive production.

My default assumption is that sources will change, runs will fail, and records will arrive late. The design has to account for that before a pipeline is done.

  1. 1

    Define the Contract

    Identify source ownership, expected freshness, grain, volume, consumers, and what a correct record means. A pipeline without a data contract becomes a debugging problem later.

  2. 2

    Choose the Processing Pattern

    Use batch when freshness requirements allow it. Use streaming when latency or event ordering justifies the added cost of checkpoints, replay, monitoring, and operational complexity.

  3. 3

    Make Failure Recoverable

    Design for retries, idempotent writes, checkpointing, dead-letter paths, and partial failure recovery. A failed run should be diagnosable and rerunnable without corrupting downstream data.

  4. 4

    Model for Consumption

    Separate raw retention, cleaning, business logic, and serving models. Facts, dimensions, marts, and aggregates should match how analysts and applications consume the data.

  5. 5

    Control Cost and Performance

    Partition large datasets, use incremental processing where possible, choose materializations deliberately, and scale compute based on workload patterns instead of leaving clusters oversized.

  6. 6

    Validate Before Trust

    Use freshness checks, uniqueness tests, null checks, reconciliation, schema validation, and anomaly detection before data reaches dashboards or business-critical workflows.

Field notes

Writing on data systems, cloud, and deployment.

All posts on Medium

Tickets & passes

Certified across Fabric, Databricks, and Airflow.

  • Fabric Data Engineer AssociateMicrosoft
  • Fabric Analytics Engineer AssociateMicrosoft
  • Azure Databricks Data Engineer AssociateMicrosoft
  • Apache Airflow FundamentalsAstronomer
  • Data Engineering Professional CertificateIBM
  • Data Warehouse EngineerIBM
  • Professional Data Engineer in PythonDataCamp
  • Data Engineer CertificationDataCamp
  • Advanced Data AnalyticsGoogle

Education

  • B.Sc. Computer Science

    Kwara State University

  • B.Sc. Statistics

    University of Ilorin

Last stop · all lines terminate here

Let's build something that holds up.

Open to remote or on-site data engineering roles: pipelines, analytics engineering, Fabric, Azure, and AWS data platforms, and the services around them.